RAG vs Long Context: When Each One Actually Wins
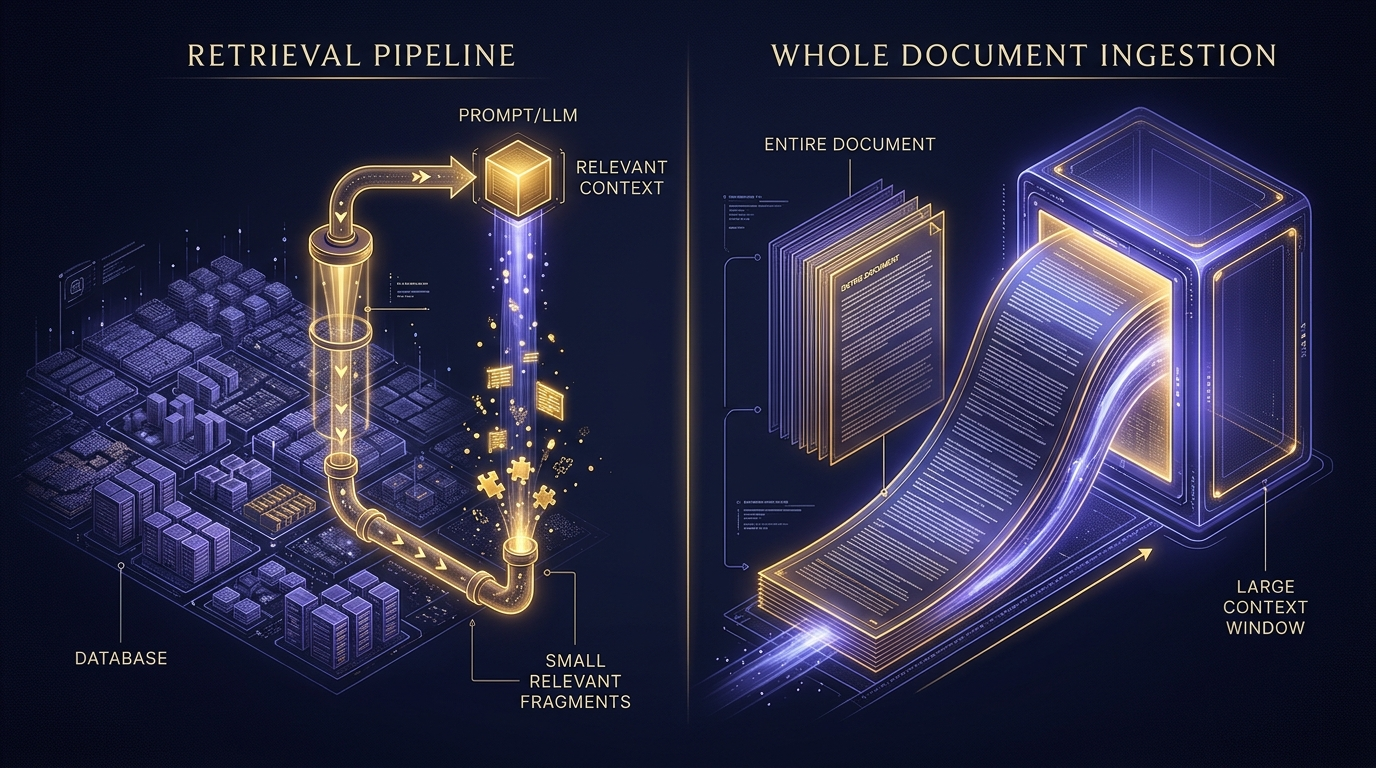
If the knowledge base is small enough to fit comfortably, changes infrequently, and the task benefits from the model reasoning across the whole thing at once (not just retrieving isolated facts), stuffing it into context is simpler and skips retrieval-quality problems entirely.
Once the knowledge base outgrows a comfortable context size, changes constantly, or needs per-query relevance filtering (most of the data is irrelevant to any given question), RAG's retrieval step earns its complexity — you're not paying to reprocess irrelevant content on every call.
Long context isn't free just because it's simple to implement — every token in that context gets billed on every call. A RAG system that retrieves only what's relevant is often cheaper at real volume even though it's more work to build.