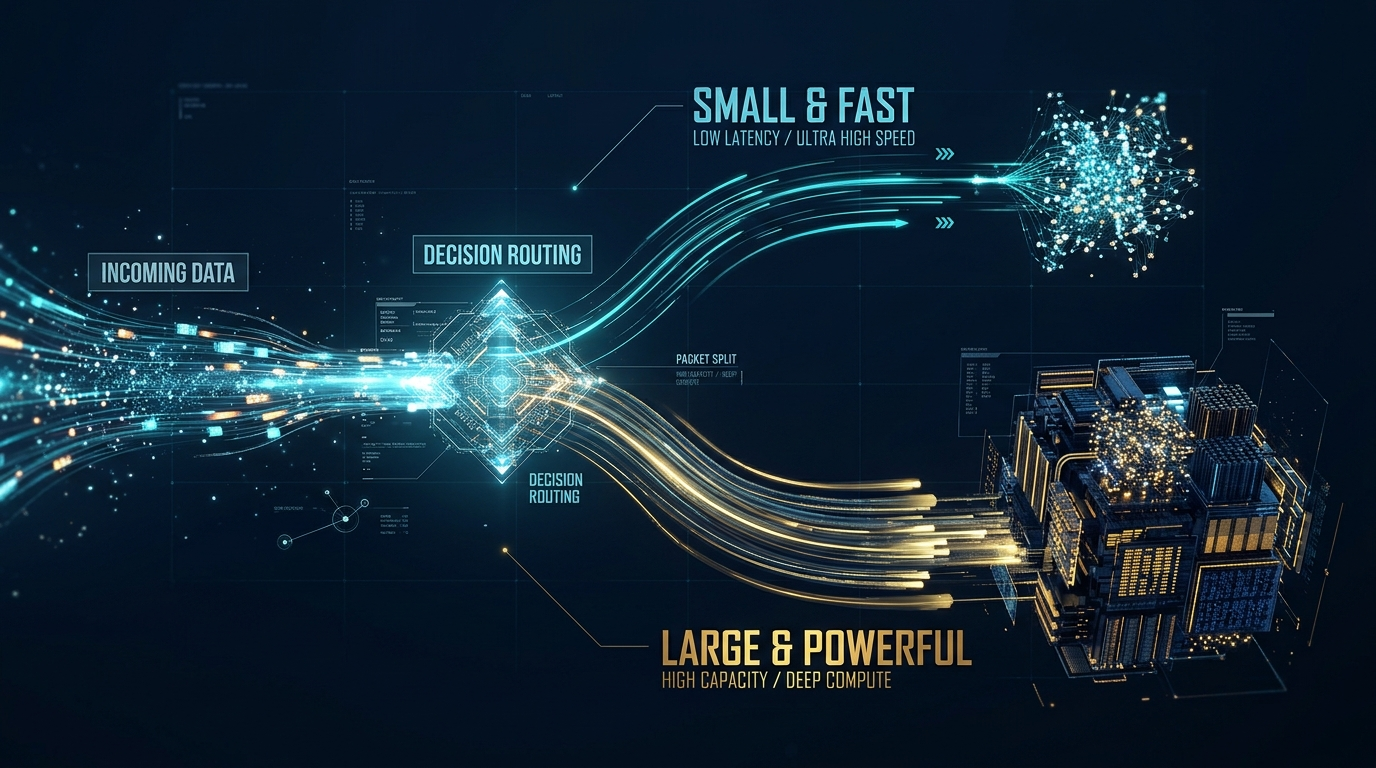
AI Model Routing: Why Using One Model for Everything Is a Mistake
Tagging a support ticket, extracting a date from an email, or classifying intent doesn't need a frontier model — it needs a fast, cheap one that gets it right 95%+ of the time. Running that through your most expensive model is pure margin loss at volume.
Route by task shape, not by vibes: structured extraction and classification go to the cheap tier by default. Anything requiring multi-step reasoning, nuance, or a decision with real consequences goes to the capable tier. Add a confidence-based escalation for the cheap tier's uncertain cases.
If your volume is low enough that the cost difference is a rounding error, don't build routing logic you now have to maintain. This is a volume optimization, not a default architecture pattern — only add it once cost actually shows up on a bill that matters.